About F5-TTS
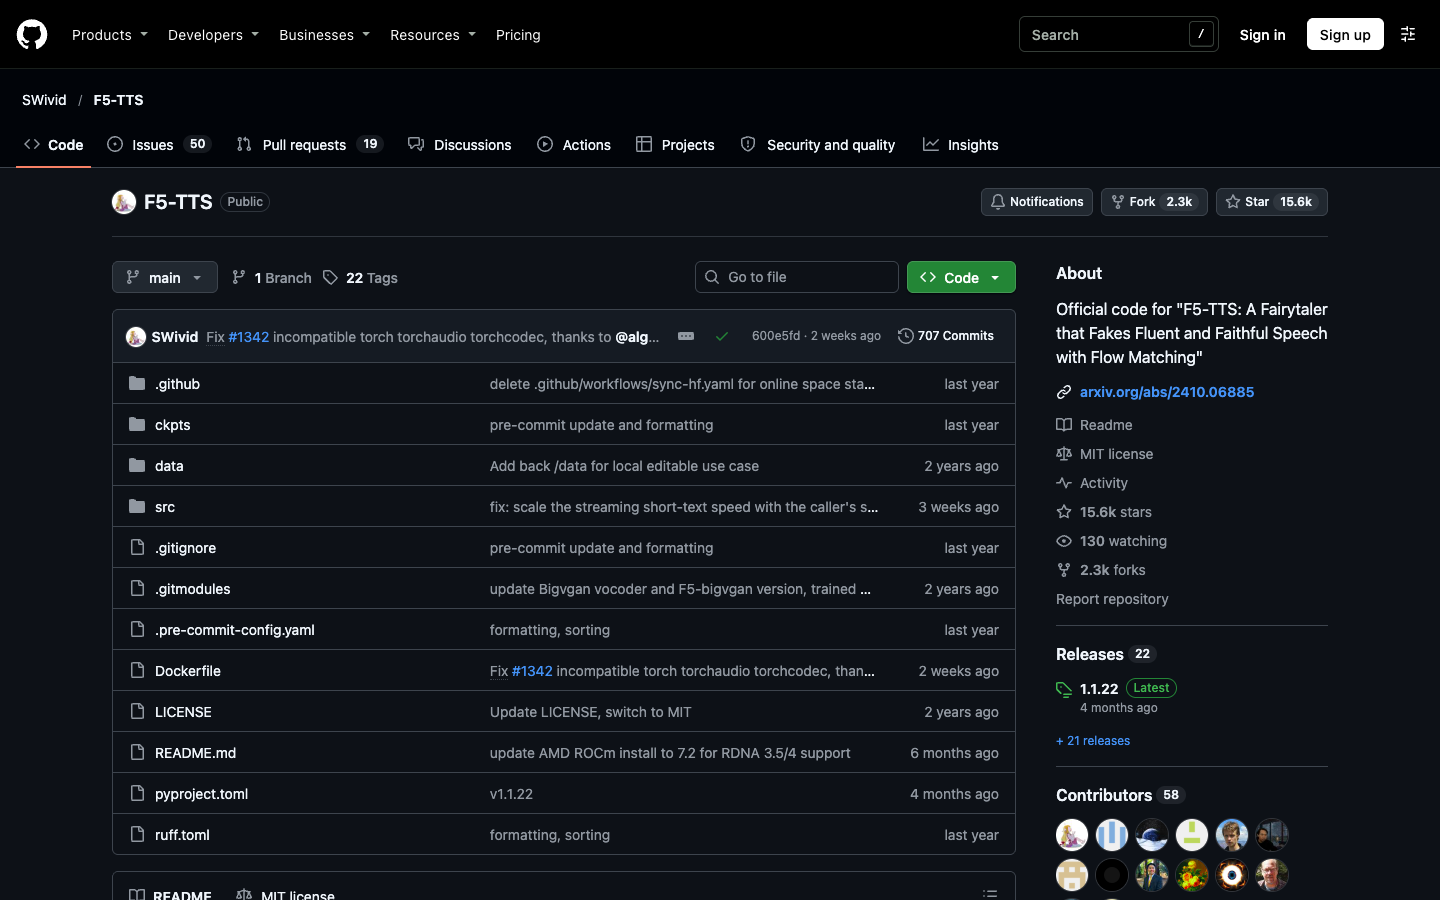
F5-TTS is the official code release for the research paper "F5-TTS: A Fairytaler that Fakes Fluent and Faithful Speech with Flow Matching". It is a diffusion transformer text-to-speech model that takes a prompt audio clip and target text and produces speech in that voice. It suits developers, researchers and technically comfortable creators who want to generate or clone voices on their own hardware.
Key benefits of F5-TTS include:
- MIT licensed: The code is open source and can be self-hosted, modified and used for finetuning or training your own models.
- Broad hardware support: Installation instructions cover NVIDIA (CUDA), AMD (ROCm on Linux), Intel GPUs and Apple Silicon.
- Gradio web interface: A local app offers basic TTS with chunk inference, multi-style and multi-speaker generation, and a voice chat mode powered by Qwen2.5-3B-Instruct.
- Multiple ways to run: Install via pip for inference, clone the repo for training, or use the published Docker image and compose example.
- Production deployment path: A Triton and TensorRT-LLM runtime is provided, with a reported real-time factor around 0.04 on a single L20 GPU.
For someone leaving ElevenLabs, F5-TTS removes per-character fees and keeps reference audio and generated speech on your own machines. The trade-offs are real: you need a capable GPU, a Python or Docker setup, and some patience with configuration, and there is no hosted service, managed API or vendor support. Results depend on your reference audio and settings, and the README recommends reading its inference guidance and searching issues when problems come up.