About Chatterbox TTS
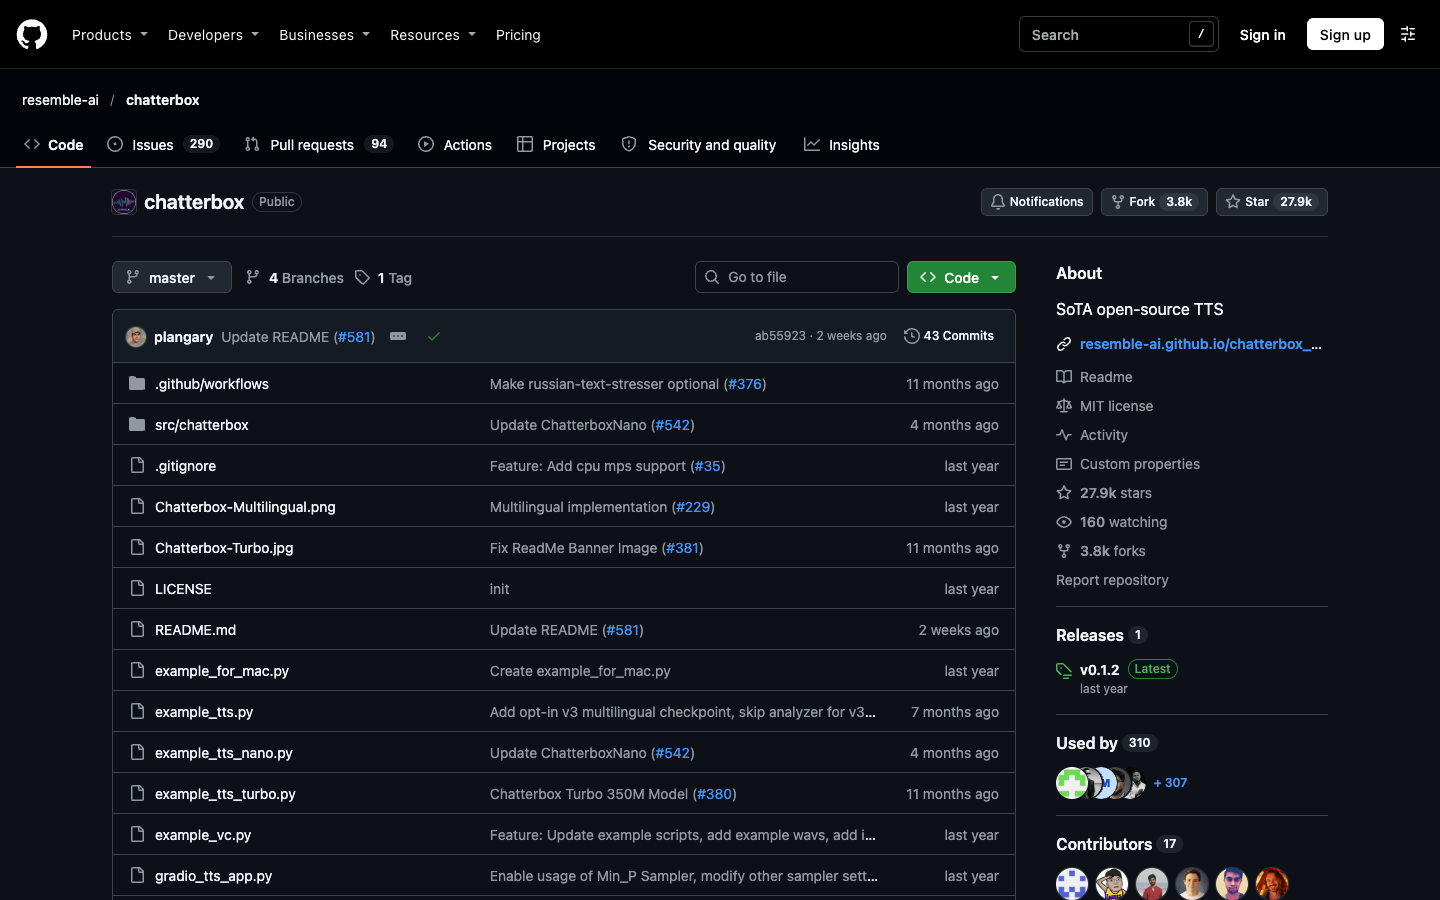
Chatterbox TTS is a family of open-source text-to-speech models released by Resemble AI under the MIT license. It is for developers who want to run speech generation and voice cloning on their own hardware with Python. As of August 2026 the project is retired research: the code stays public as an archive with no support, updates or paid tier.
Key benefits of Chatterbox TTS include:
- Several model sizes: Turbo (350M), Nano (110M) and Multilingual V3 (500M) cover voice agents, CPU-only devices and multilingual use.
- Voice cloning from a reference clip: Models generate speech in a voice taken from a short reference audio sample.
- Paralinguistic tags: Turbo and Nano support tags like [laugh], [cough] and [chuckle] inside the text.
- Multilingual support: Multilingual V3 covers 23+ languages, plus a Single Language Pack of six dedicated finetunes.
- CPU inference: Nano runs about 3x faster than realtime on 8 CPU cores, according to the README.
For someone leaving ElevenLabs, Chatterbox means no per-character billing and no audio sent to a third party: install it with pip install chatterbox-tts and run it locally, with Gradio demo apps included. The trade-offs are real. There is no hosted interface, you manage your own GPU or CPU setup, and the project is no longer maintained, so bugs and dependency issues will not be fixed upstream. It is best suited to teams comfortable owning and forking the code.